Vanessa and diffractor introduce a new approach to epistemology / decision theory / reinforcement learning theory called Infra-Bayesianism, which aims to solve issues with prior misspecification and non-realizability that plague traditional Bayesianism.
Linkpost for https://arxiv.org/html/2611.14454v1
Our PIBBSS fellow Damini Kusum wrote an excellent paper on prediction with reflective oracle Solomonoff Induction (rOSI).
Reflective oracles are best known for their game-theoretic applications, where they are often dismissed because "why would all players choose the same reflective oracle?"
It turns out that reflective oracles can also be used to construct a version of Solomonoff induction (called rOSI) with very nice sequence prediction properties - roughly speaking, it can learn to extract computable structure from (partly) uncomputable sequences. In fact, its properties are quite reminiscent of logical induction, but this paper is much shorter and more accessible. In this context, there is only one "player" to choose an oracle, which is just a fixed-point (though you can sort of consider the set of hypotheses entertained by that player as subplayers who share the oracle).
I think this paper is the clearest exposition of a very neat but previously obscure idea in agent foundations: self-reflection can overcome unrealizability.
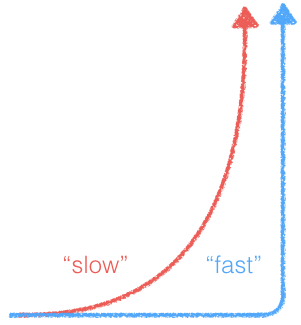
This is a transcription of Eliezer Yudkowsky responding to Paul Christiano's Takeoff Speeds live on Sep. 14, followed by a conversation between Eliezer and Paul. This discussion took place after Eliezer's conversation with Richard Ngo.
Color key:
| Chat by Paul and Eliezer | Other chat | Inline comments |
[Yudkowsky][10:14] (Nov. 22 follow-up comment) (This was in response to an earlier request by Richard Ngo that I respond to Paul on Takeoff Speeds.) |
[Yudkowsky][16:52] maybe I'll try liveblogging some https://sideways-view.com/2018/02/24/takeoff-speeds/ here in the meanwhile |
[Yudkowsky][16:57]
![]() It seems to me to be... |
I’m not 100% convinced of this, but I’m fairly convinced, more and more so over time. I’m hoping to start a vigorous but civilized debate. I invite you to attack my weak points and/or present counter-evidence.
My thesis is that intent-alignment is basically happening, based on evidence from the alignment research in the LLM era.
The classic story about loss of control from AI is that optimization pressure on proxies will cause the AI to value things that humans don’t. (Relatedly, the AI might become a mesa-optimizer with an arbitrary goal).
But the reality that I observe is that the AIs are really nice and somewhat naive. They’re like the world’s smartest 12-year-old (h/t Jenn). We put more and more RL optimization pressure, and keep getting smarter and smarter models; but they...
I used to think of "automating alignment" as a natural category. But when I tried to think through the strategic implications, I realised that it depends a lot on the type of work. I'm now thinking of it in three buckets:
In the rest of this post I'll walk through my current takes on these in terms what’s needed for automation, how good or bad they look, what our priorities might...